Mar 19, 202621 min
Tired of wasted compute? UC Berkeley is addressing the inefficiencies of exclusive GPU access by proposing a unified resource management layer to enable multitasking, potentially reclaiming the 90% of resources often...


Dive deep into the exciting realm of Generative AI without the jargon! 🚀 Here, we transform the latest GenAI technologies – sourced from pioneering research papers and top blogs – into easy-to-follow podcast discussions. Join our community of AI enthusiasts, learn something new every week, and become a GenAI expert with us!
Required Pod Score for this podcast. PitchCentric checks your profile against host openness, topical fit, and audience signals before you generate a pitch.
Contact path
Public web form
Booking probability
25%
Guest openness
Selective
Sign up to generate a grounded pitch for GenAI Learner.
Signup to Generate a PitchDive deep into the exciting realm of Generative AI without the jargon! 🚀 Here, we transform the latest GenAI technologies, sourced from pioneering research papers and top blogs, into easy-to-follow podcast discussions. Join our community of AI enthusiasts, learn something new every week, and become a GenAI expert with us!
Recent episodes include "Beyond Singletasking: Building an Operating System for Your GPU" (19 March 2026, 21 minutes), "Scaling AI: Think Operators, Not Models" (15 November 2025, 12 minutes), and "Can AI Learn Like Humans? The Novel Games Benchmark" (13 November 2025, 12 minutes).
GenAI Learner publishes roughly daily, with episodes averaging 17 minutes across 29 episodes.
Booking probability for GenAI Learner is 25%, and the host is rated Selective on guests. GenAI Learner requires a Pod Score of 80 or higher. GenAI Learner's contact route on record: public web form.
The strongest fits for GenAI Learner are IT Services & Software Development and Scientific Research & Development. GenAI Learner has a technology audience.
GenAI Learner is a technology podcast with 29 episodes published.
Our AI reads these to draft pitches. Use them as grounding for a pitch that cites a real guest and a specific topic.
Tired of wasted compute? UC Berkeley is addressing the inefficiencies of exclusive GPU access by proposing a unified resource management layer to enable multitasking, potentially reclaiming the 90% of resources often...

Episode #28
Scaling large AI models to meet dynamic traffic is slow and leads to significant resource waste. Researchers at Microsoft Azure Research and Rice University are rethinking this process, finding that scaling the entire...
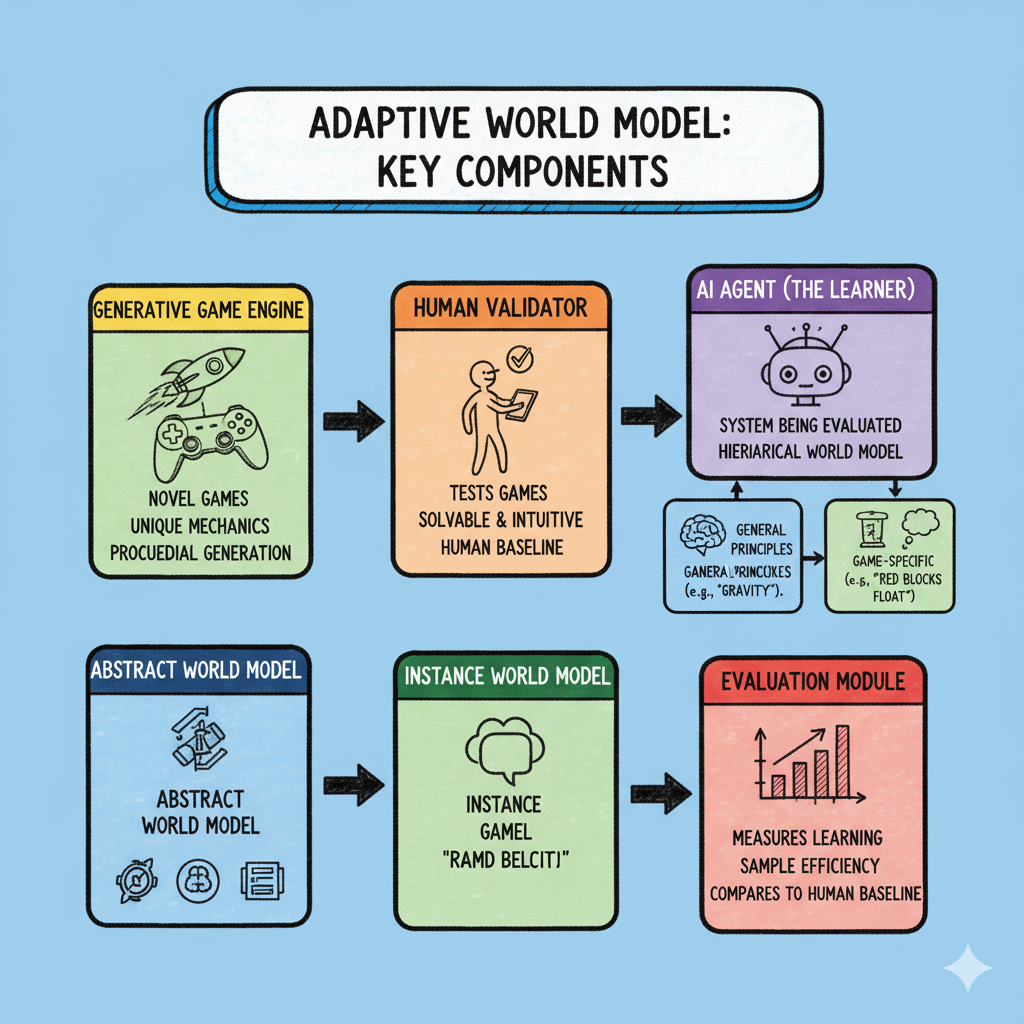
Researchers at MIT and Harvard argue that true intelligence requires constructing internal world models, proposing a generative game benchmark to prove if AI can adapt to unseen environments without millions of training...

The Surprising Limits of RL in LLM Reasoning Arxiv: https://arxiv.org/pdf/2504.13837The promise of RL for LLM growth hits a wall: Tsinghua University's study shows RLVR only improves efficiency but is bounded by and...

Research from Samsung SAIL Montréal introduces the Tiny Recursive Model (TRM), which uses a single, 2-layer network to outperform massive LLMs on tough puzzles like ARC-AGI. Arxiv: https://arxiv.org/pdf/2510.04871 Hear...
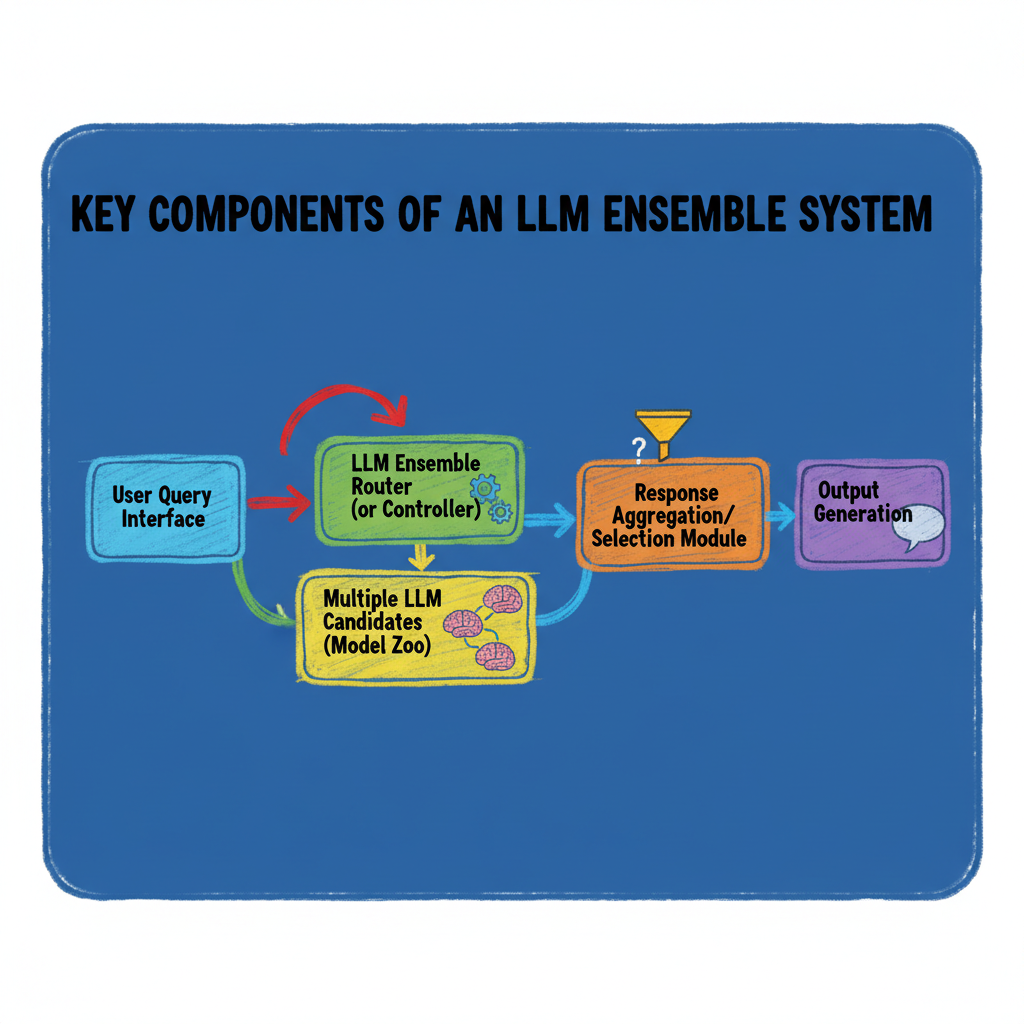
Ensemble LLMs: The Power of Multiple AI Minds Arxiv: https://arxiv.org/pdf/2502.18036 The LLM Commitee: Why 182,000 AI Models Aren't Enough and How Ensembles Beat the Single Perfect Oracle? Why rely on one LLM when you...
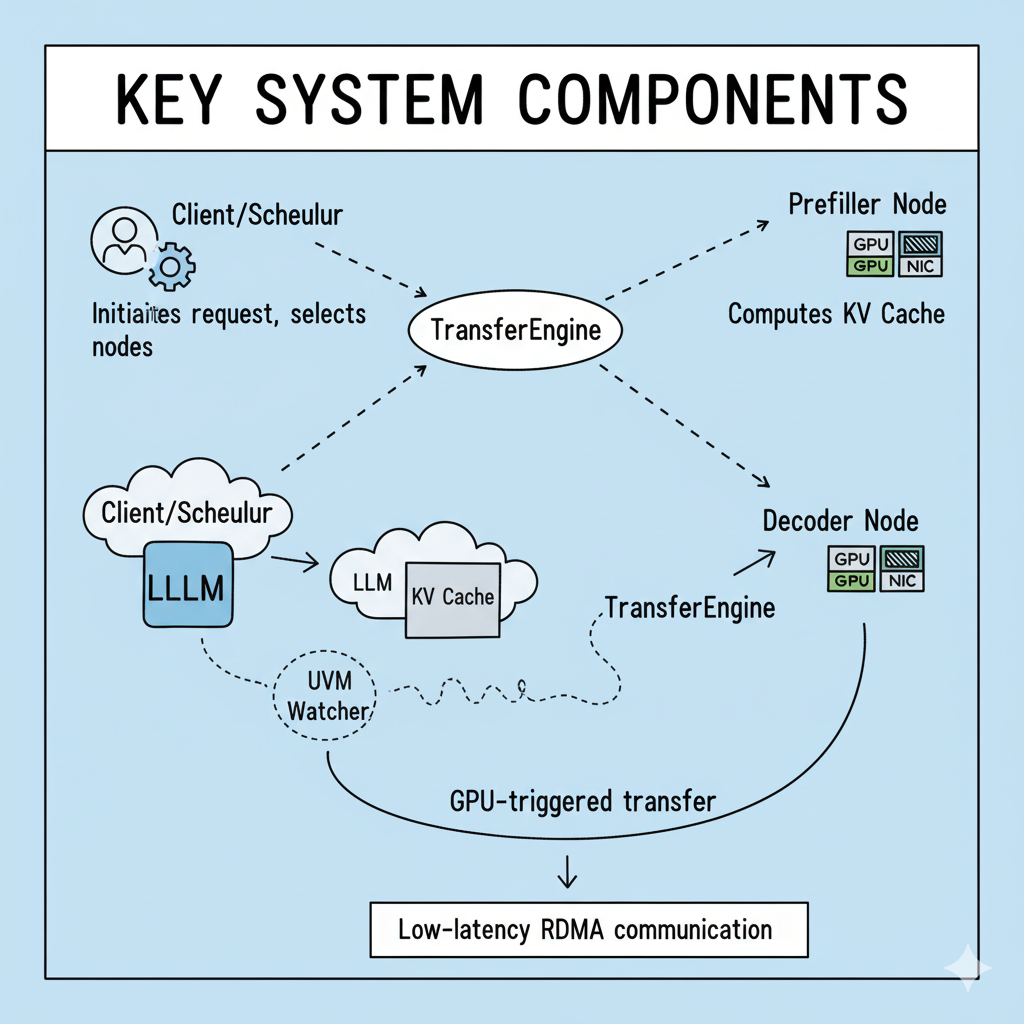
Cloud wars over custom hardware? Perplexity AI solved it. Discover the TransferEngine provides a portable, vendor-agnostic RDMA point-to-point communication interface for LLM systems, avoiding hardware lock-in with a...
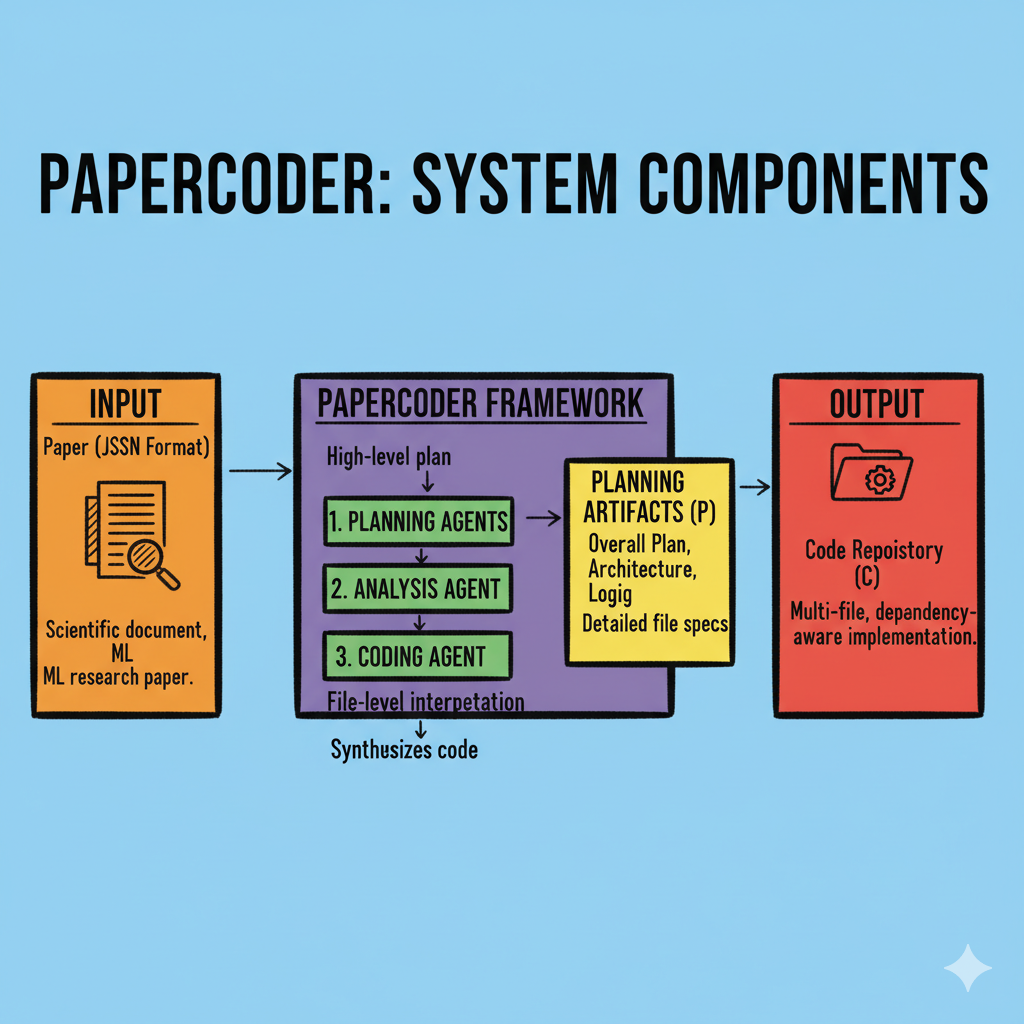
Straight from KAIST, the revolutionary PaperCoder automates functional code generation from raw machine learning papers, and the "GenAI learner" podcast breaks down this multi-agent LLM framework simply. Arxiv...

How to Learn Games in Minutes (No NNs!) Researchers at VERSES AI built a new AI agent that masters games in minutes without using neural networks or gradient optimization. Arxiv: https://arxiv.org/abs/2505.24784 The...

Episode #20
Researchers at Meta just taught LLMs to reason without language, letting them explore multiple paths simultaneously. Arxiv: https://arxiv.org/abs/2412.06769v1 The GenAI Learner podcast breaks down how this "COCONUT"...
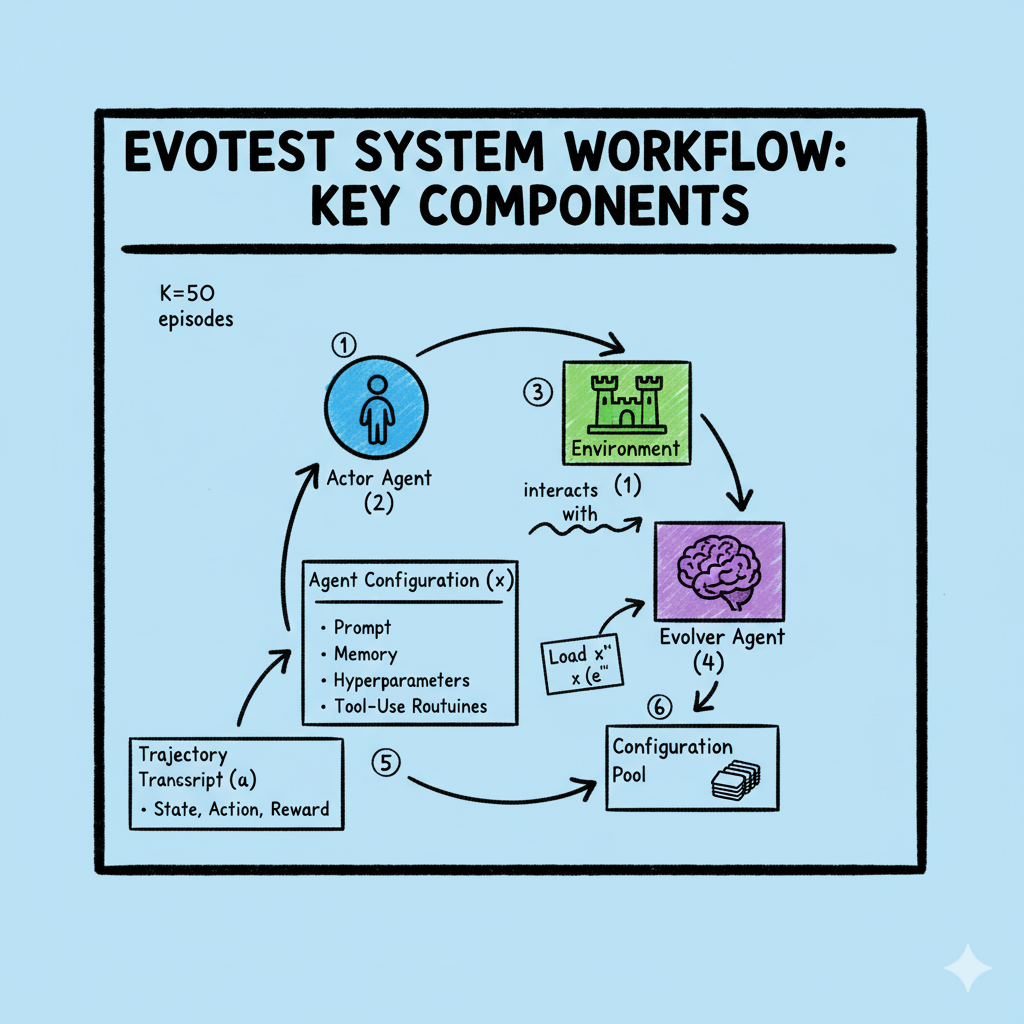
A new system from Microsoft Research shows how EvoTest evolves an agent's entire configuration using narrative transcript analysis, outperforming gradient-based and reflection methods. Arxiv...

An individual's DreamCoder-inspired method proved to be the most performance-cost efficient approach to the complex ARC-AGI Prize challenge. Original Article: https://substack.com/home/post/p-172998849 Understand the...

Jeremy Berman's Substack reveals a state-of-the-art 79.6% ARC-AGI score by using an evolutionary process that refines plain English instructions instead of code—tune into GenAI learner for a simple breakdown...
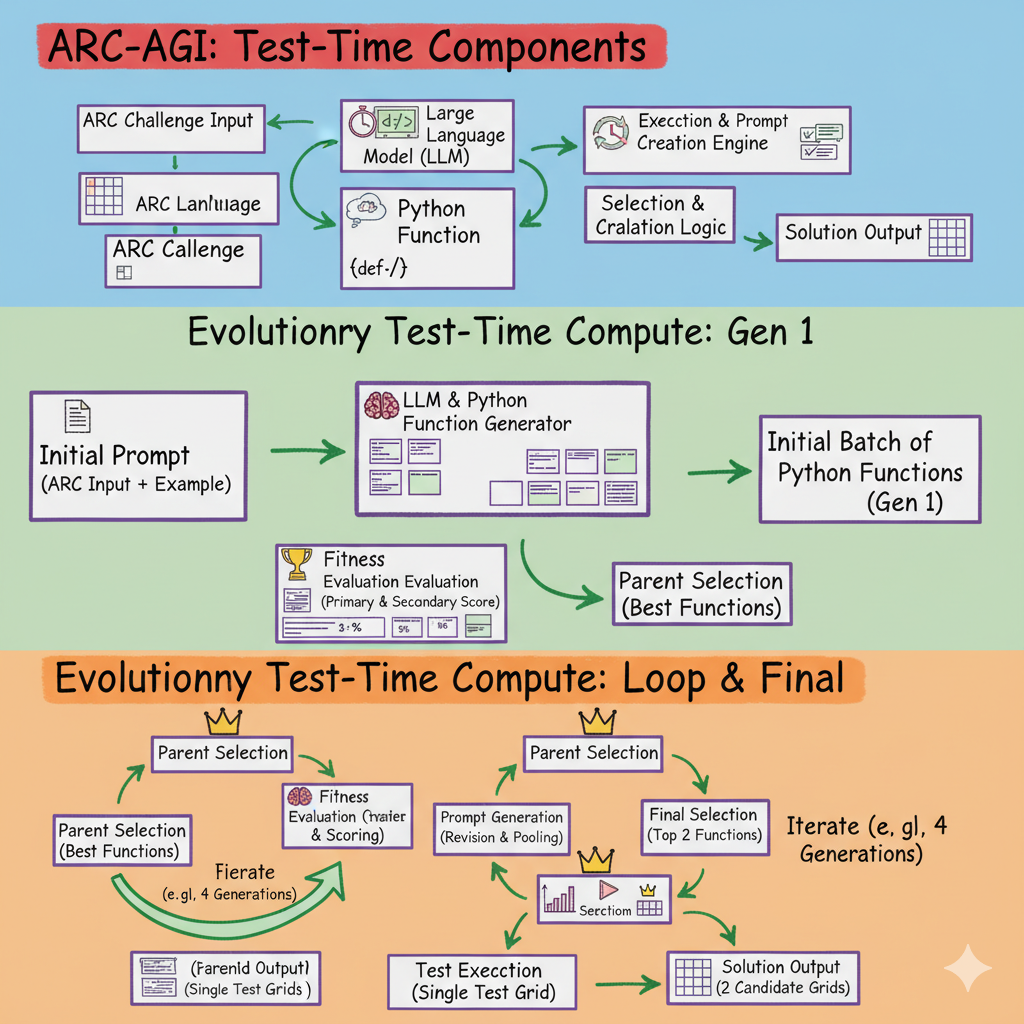
Hear how Anthropic's Sonnet 3.5 smashed the ARC-AGI record by using Evolutionary Test-time Compute to overcome generalization limits. Substack: https://jeremyberman.substack.com/p/how-i-got-a-record-536-on-arc-agi Get...
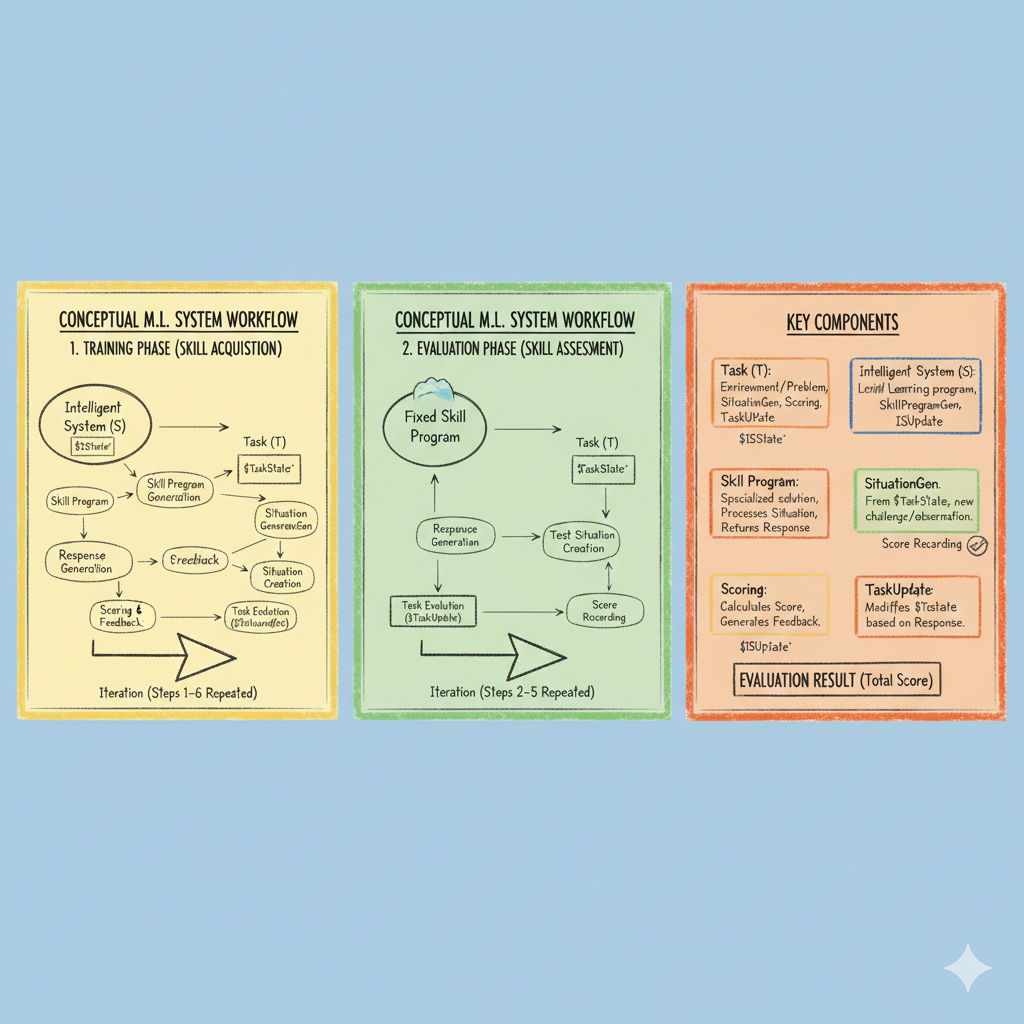
Google, Inc.'s François Chollet argues that we should stop measuring AI's performance and start measuring intelligence as the efficiency of skill acquisition over a range of tasks, accounting for priors and experience...

Episode #14
The ARC Prize Foundation just dropped ARC-AGI-2, a new, harder AI benchmark designed to assess general fluid intelligence at higher cognitive complexity levels. Arxiv: https://arxiv.org/abs/2505.11831 Tune into GenAI...

ARC Prize 2024 revealed that Test-Time Training (TTT) and program synthesis drove the state-of-the-art ARC-AGI score from 33% to 55.5%. Arxiv: https://arxiv.org/abs/2412.04604 Tune into GenAI Learner for a simple...

Researchers from Tencent and Renmin University of China discovered the reasoning reward equals a last-token self-rewarding score, a game-changer for efficient LLM verification—get the simple breakdown on GenAI Learner...

Wonder why LLMs struggle with multi-step logic? A new paper from MBZUAI shows the Fano-style accuracy upper bound proves single-pass LLM reasoning collapses when task complexity exceeds output capacity. Arxiv...
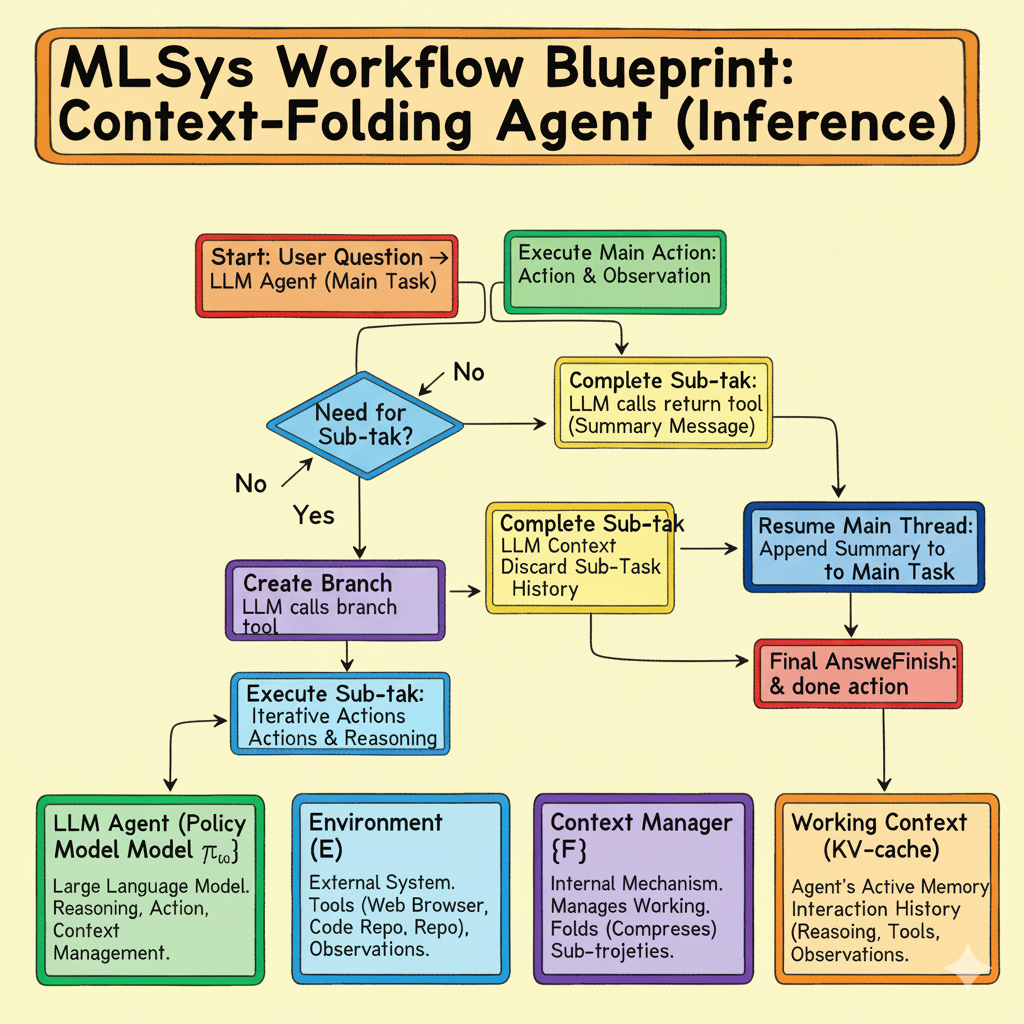
Engineers from ByteDance and Carnegie Mellon University just scaled LLM agents 10x with Context-Folding, a method that summarizes complex sub-tasks to manage memory. Arxiv: https://arxiv.org/abs/2510.11967 Get the...
PitchCentric classifies GenAI Learner under these industries. Guests from them are the closest fit, and each links to the best podcasts in that industry.
Shows with the most semantically similar episode content. Pitch one, pitch all; producers cluster.
Is this podcast yours and you'd like to remove or correct details? Request removal or email privacy@pitchcentric.com.
Questions about the free trial? See the pricing FAQ